%22%3E%3C/path%3E%3Cpath d=%22M 63.072 7.554 C 62.258 8.022 61.577 8.689 61.092 9.493 L 61.092 7.076 L 57.158 7.076 L 57.158 22.64 L 61.089 22.64 L 61.089 14.888 C 61.089 13.446 61.403 12.434 62.03 11.853 C 62.818 11.218 63.818 10.907 64.826 10.982 L 65.868 10.982 L 65.868 6.851 C 64.891 6.834 63.926 7.076 63.073 7.554 Z%22 fill=%22rgb(17,17,17)%22%3E%3C/path%3E%3Cpath d=%22M 78.916 7.82 C 76.363 6.49 73.321 6.49 70.768 7.82 C 69.562 8.473 68.564 9.451 67.888 10.644 C 67.167 11.931 66.803 13.387 66.834 14.862 C 66.804 16.332 67.157 17.785 67.86 19.077 C 68.515 20.267 69.494 21.246 70.684 21.901 C 71.924 22.576 73.318 22.92 74.73 22.898 C 76.164 22.918 77.58 22.575 78.846 21.901 C 80.062 21.247 81.073 20.27 81.768 19.077 C 82.506 17.797 82.88 16.339 82.85 14.862 C 82.88 13.389 82.517 11.934 81.797 10.647 C 81.12 9.455 80.122 8.477 78.917 7.824 M 78.803 14.862 C 78.829 15.739 78.636 16.608 78.241 17.391 C 77.903 18.046 77.38 18.588 76.738 18.95 C 76.124 19.293 75.432 19.472 74.729 19.47 C 73.668 19.497 72.648 19.061 71.934 18.276 C 71.139 17.323 70.741 16.1 70.823 14.862 C 70.741 13.62 71.149 12.395 71.959 11.45 C 72.687 10.667 73.715 10.233 74.783 10.256 C 75.859 10.236 76.894 10.67 77.635 11.45 C 78.464 12.387 78.884 13.616 78.801 14.864%22 fill=%22rgb(17,17,17)%22%3E%3C/path%3E%3Cpath d=%22M 95.906 7.076 L 95.906 15.646 C 95.975 16.68 95.643 17.701 94.979 18.498 C 94.311 19.184 93.379 19.547 92.422 19.495 C 91.475 19.544 90.553 19.18 89.894 18.498 C 89.23 17.701 88.898 16.68 88.967 15.646 L 88.967 7.076 L 85.033 7.076 L 85.033 16.207 C 85 17.449 85.275 18.68 85.834 19.79 C 86.327 20.75 87.095 21.542 88.039 22.065 C 89.033 22.594 90.145 22.861 91.271 22.838 C 92.188 22.847 93.095 22.65 93.926 22.263 C 94.708 21.905 95.388 21.36 95.906 20.675 L 95.906 22.645 L 99.865 22.645 L 99.865 7.076 Z%22 fill=%22rgb(17,17,17)%22%3E%3C/path%3E%3Cpath d=%22M 4.513 15.626 C 4.511 10.815 7.606 6.549 12.181 5.059 C 16.756 3.57 21.77 5.195 24.601 9.086 L 27.816 5.87 C 24.074 1.186 17.981 -0.943 12.137 0.393 C 6.292 1.728 1.728 6.292 0.393 12.137 C -0.943 17.981 1.186 24.074 5.87 27.816 L 9.085 24.601 C 6.214 22.512 4.515 19.177 4.513 15.626%22 fill=%22rgb(32,62,235)%22%3E%3C/path%3E%3Cpath d=%22M 17.114 14.343 L 13.354 18.01 L 13.354 18.026 L 21.071 18.026 L 11.412 27.609 L 17.389 27.609 L 23.999 21.081 L 23.999 28.316 L 24.005 28.316 L 27.967 24.393 L 27.967 14.343 Z%22 fill=%22rgb(32,62,235)%22%3E%3C/path%3E%3C/g%3E%3C/svg%3E) ×
 ××
›
›
›
›
Data orchestration platforms for B2B revenue teams in 2026
Data orchestration platforms for B2B revenue teams in 2026
Data orchestration platforms for B2B revenue teams in 2026
Data orchestration platforms for B2B revenue teams in 2026
Data orchestration platforms for B2B revenue teams in 2026
Data orchestration platforms for B2B revenue teams in 2026
Author
Aljaz Peklaj

Your stack is busy, but your pipeline still feels blind. Leads land in LinkedIn, email, paid channels, and your CRM. Replies split across inboxes. Hand-offs stall. By the time someone asks why qualified meetings are flat, the team is already arguing over whose report is right.
The core issue is usually coordination, not volume. Fragmented systems make ownership, failures, and dependencies harder to see.
A data orchestration platform gives revenue teams state, retries, and traceability. That's what turns scattered activity into a controlled pipeline.
The buying decision is as much about governance as tooling. Ownership, definitions, and escalation paths matter more than feature checklists.
The practical test is simple. If your stack can't explain what ran, what broke, and what reached CRM, it's not ready.
For teams who need gain visibility into your sales pipeline, the pattern is familiar. You can see activity everywhere, but you can't trust the handoff from signal to revenue. GROU sees the same problem in iGaming, SaaS, manufacturing, legal tech, and pharma, and the fix starts with structure, not more tools. See also data hygiene.
Table of Contents
How orchestration differs from ETL, ELT, and basic workflows
Use cases across iGaming, SaaS, manufacturing, legal tech, and pharma
Why pipeline data usually breaks before it reaches revenue
A rep replies in Gmail, a marketer sees engagement in LinkedIn, and the CRM still shows a stale stage. That mismatch is where pipeline data usually breaks. One system records activity, another assigns ownership, and a third waits for a clean update that never arrives.
The result is familiar in RevOps. Activity reports can look healthy while qualified meetings stay flat, because the stack rewards motion instead of outcomes. Sends rise, clicks rise, connection requests rise, and the team still cannot explain why the pipeline is not moving.
Practical rule: if the same prospect exists in three tools with three different statuses, the problem is orchestration.
Clean reporting starts with visibility, then coordination, then tooling. Many teams try to fix the last step first, which only adds more software on top of the same disconnect. If you need a deeper explanation of the pattern, gain visibility into your sales pipeline is a solid companion read.
For revenue teams, the failure usually shows up in ordinary work. A form fill should route to the right owner. A positive reply should reach sales fast. A bad enrichment call should not pollute the CRM. A missed dependency can break all four, and the issue often stays hidden until a forecast review or a quarter-end scramble.
That is also why data hygiene matters here. Clean inputs, clear ownership, and consistent definitions keep orchestration useful instead of turning the stack into a junk drawer. When those basics slip, outbound signals scatter, routing gets unreliable, and qualified pipeline becomes harder to trust.
What a data orchestration platform does
A serious orchestration layer treats work as a directed acyclic graph, or DAG. Each node is a task. Each edge is a dependency. That structure matters because the scheduler only triggers what is ready, and a revenue stack cannot afford random execution order.

The control plane decides, the workers execute
The split that matters is scheduling versus execution. The control plane checks state. The executor runs the work. That separation keeps slow jobs from blocking fast decisions, which matters when one path is a quick reply router and another is a slower enrichment or scoring job.
Apache Airflow makes that separation explicit through its scheduler, executor, webserver, DAG definitions, and metadata database, and its DAG abstraction models task dependencies, data flow, and retries (Airflow architecture overview). That structure gives you a traceable record of what ran, when it ran, and why a task retried.
For revenue operations, the same pattern coordinates enrichment, deduplication, scoring, CRM sync, attribution, and alerts without turning each step into its own island. A workflow only helps if the system can preserve order, retry safely, and show where the chain broke. That is why a low-code wrapper can be useful, but only if the dependency model underneath is real, as explained in how a low code platform works. See our GTM orchestration overview for how this maps to pipeline workflows.
Idempotency is the feature that saves you later
The quiet requirement is idempotency. If a task reruns, it should not duplicate a record or fire the same downstream action twice. That is not a nice-to-have. It keeps a failed enrichment retry from sending duplicate alerts or updating the CRM incorrectly.
One clean retry policy beats three manual fixes after the fact.
Orchestration differs from a pile of scripts because scripts can move data, while orchestration preserves state, manages dependency order, and makes failure visible before it corrupts a downstream handoff. For B2B teams, that is the difference between a reliable pipeline and a set of disconnected automations.
How orchestration differs from ETL, ELT, and basic workflows
ETL and ELT describe movement and transformation. Orchestration sits above them and decides how the whole chain behaves when conditions change. That's why the recommendation is straightforward, not neutral.
Pick the layer that matches the job
Use ETL or ELT when the main task is data movement or transformation. Use a workflow engine when the sequence is simple and linear. Choose a data orchestration platform when the stack has many dependencies, retries, handoffs, and audit needs that can't be handled well by a straight-line job.
Option | What it does well | Where it falls short |
|---|---|---|
ETL or ELT | Moving and transforming data | Weak on dependency control and failure isolation |
Basic workflow tools | Linear task sequences | Limited state management and replay logic |
Data orchestration platform | Coordinating distributed steps with retries and observability | More setup, but far better control |
For mid-market B2B pipeline stacks, the verdict is usually clear. If you're only moving a few datasets on a schedule, a lighter tool is fine. If lead routing, enrichment, CRM sync, attribution, and reporting all depend on one another, orchestration earns its place quickly.
That's the line many teams cross when they grow out of ad-hoc jobs. They no longer need “something that runs.” They need something that can explain what happened, recover cleanly, and keep downstream systems from acting on broken inputs. The distinction is easy to miss until the first serious incident.
See the workflow glossary entry if you want a quick shorthand for how a workflow differs from a coordinated orchestration layer.
Core capabilities that matter for B2B pipeline teams
The most useful capabilities are the ones that keep bad records out of the CRM and keep good records moving. That starts with a single target list, shared by outreach and reporting, so one prospect doesn't become three conflicting versions of truth. It also means route rules, scoring logic, and attribution updates have to behave the same way every time.
The capabilities that protect revenue quality
Capability | Pipeline impact | When it matters most |
|---|---|---|
Verified prospect data | Reduces wasted sends and bad routing | Before first outreach goes live |
Unified reply tracking | Prevents channel-level blind spots | When email and LinkedIn run together |
Explicit enrichment and scoring rules | Keeps ad-hoc scripts out of the core motion | When handoffs depend on qualification |
Retry and quarantine logic | Stops broken tasks from polluting CRM | When upstream vendors or APIs fail |
Audit logging | Preserves decision history for compliance | When prospect data affects routing or suppression |
A failed enrichment call should not push incomplete records downstream. It should retry under a defined policy, then quarantine if the error persists. That's a lot less glamorous than “automation,” but it's what keeps sequences from firing on bad data.
Recovery mechanics matter more than glossy dashboards
Documented enterprise workflow behavior includes detecting failure, applying retry policies, isolating the failed step, and resuming from the right recovery point rather than restarting the whole pipeline (enterprise workflow recovery behavior). That's the difference between a controlled exception and a silent data mess.
For teams handling European prospect data, compliance logging matters just as much. UK GDPR guidance says that when solely automated processing produces a legal or similarly significant effect, people need safeguards including human intervention, the ability to express their viewpoint, the ability to contest the decision, and access to an explanation of the logic (UK GDPR guidance on AI systems). CNIL also says personal data must be appropriate, relevant, and limited to what's necessary for the purpose, with human review available where automated decisions are used (CNIL guidance on AI and GDPR).
See the RevOps tech stack guide if you want to place orchestration in the rest of the stack, not treat it like a standalone toy.
Use cases across iGaming, SaaS, manufacturing, legal tech, and pharma
Orchestration shows its value when one revenue motion depends on several signals at once. In iGaming, that usually means ad engagement, intent, and outbound activity feeding the same pipeline. In SaaS, the difference is visible in the handoff, a list that produces replies is not the same as a list that produces accepted meetings.
iGaming and adjacent demand capture
Sportradar needed a structured way to capture demand from sportsbooks and betting companies across EMEA. Campaigns ran across LinkedIn, Google, Reddit, RichAds, and 6sense, all feeding one pipeline instead of separate reports. Reported results from that demand-capture program included 800+ qualified leads at €15 per lead, with 80% qualifying as SQLs (Sportradar example).
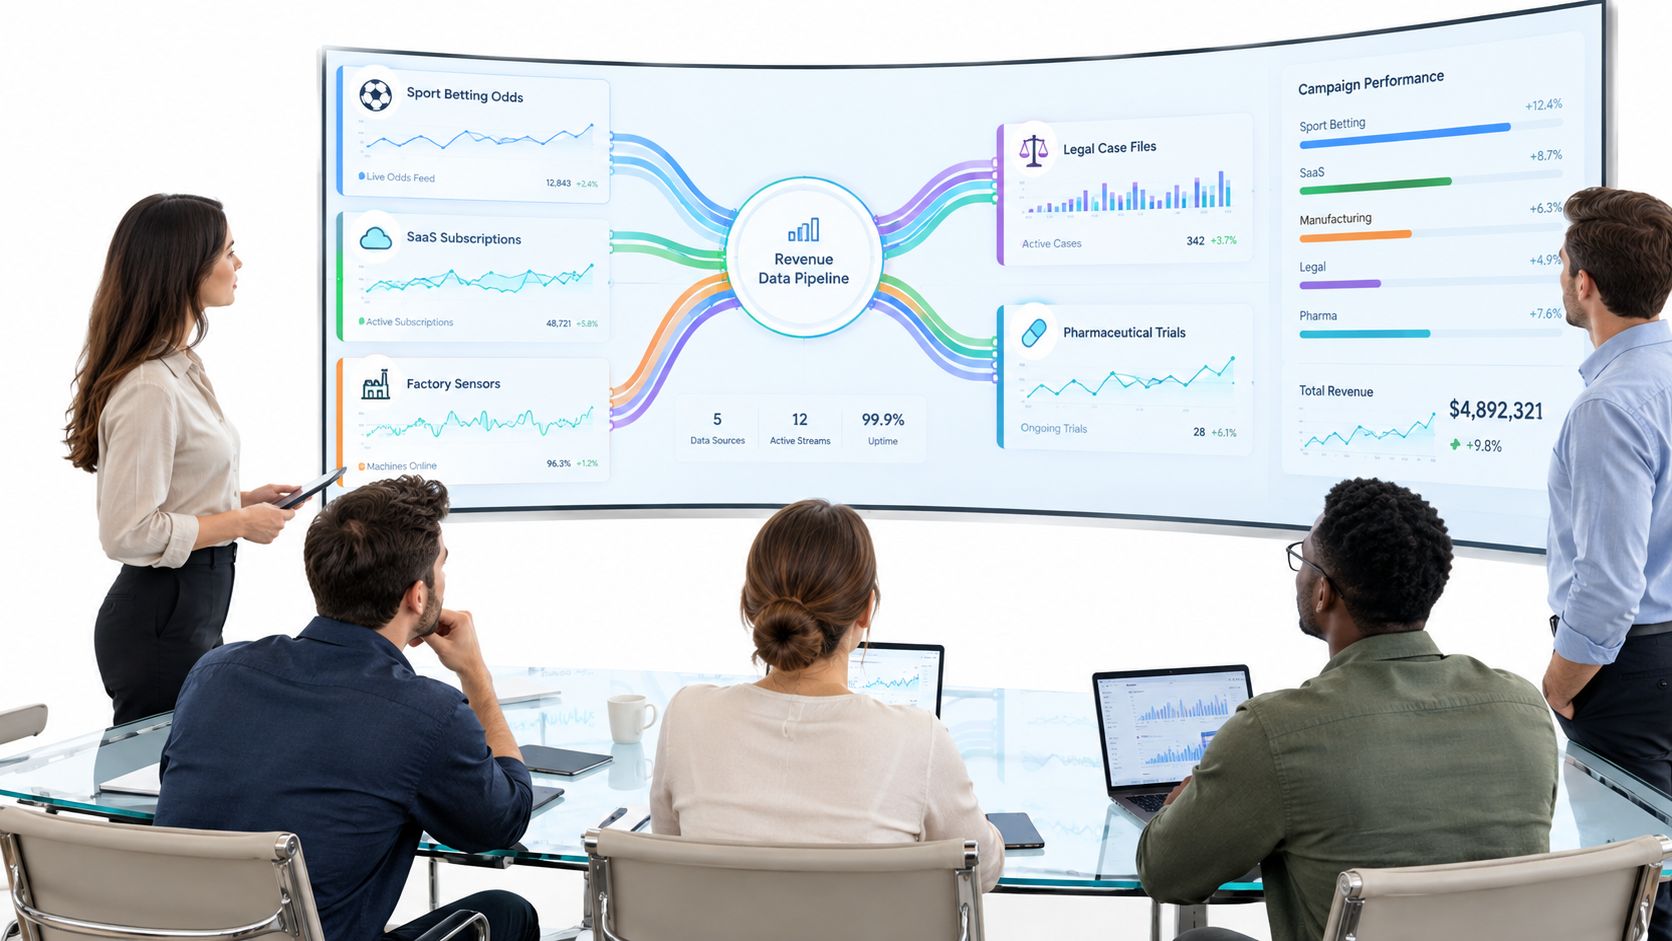
The point is not which channel “won.” The point is that one pipeline made the mix measurable. Without that structure, each source ends up in its own dashboard, with its own story, and RevOps has no clean way to connect spend to meetings. For teams working in iGaming, this industry page shows how the same coordination problem shows up across demand capture, lead handling, and reporting.
What the unified motion exposes
Unified data makes it easier to see where multichannel outreach beats email-only programs. MBF saw that pattern in its own outreach, and T-2's IT segment reached a 19.2% reply rate, compared with an 11.8% average, once email and LinkedIn were measured in one list. A source that discusses practical workflow coordination in similar programs is the reply-rate example.
The same structure matters in manufacturing, legal tech, and pharma, even when the message changes. The core work is keeping source, message, response, and CRM outcome tied together. Without that chain, attribution becomes decoration instead of a decision tool.
Ownership, not connector work, is where these projects stall. A 2026 survey found that legacy systems and technical debt were the leading bottleneck at 25.4%, followed by lack of leadership direction at 21.3% and poor requirements or upstream issues at 18.8%. Tool complexity was only 2.7%, which points to a familiar RevOps problem, the stack is rarely the hardest part, alignment is. (survey on data engineering bottlenecks)
How to evaluate and implement a data orchestration platform
Start with governance, not features. If nobody agrees on what counts as a sales-accepted lead, an SQL, or an attributed pipeline touch, the platform just automates disagreement. Ownership, escalation paths, and handoff rules need to be settled before any vendor demo starts.
The second filter is cost visibility. A 2026 survey of 113 data professionals found that 44 percent of organizations spent between $25,000 and $100,000 per month on their data stack, while only 12 percent felt they were receiving strong ROI from it (survey on data stack costs). That makes workload-level attribution essential, because a single platform can hide waste if nobody tracks what each pipeline really costs.
A practical implementation sequence
Start with three sources in this order, because the dependency chain matters. First, verified prospect data. Second, outreach activity across email and LinkedIn. Third, the CRM. That sequence keeps the target list, the message, and the outcome tied together from the start.
The order matters because data quality decides deliverability, reply rate, and lead quality. Each record should carry more than a name and email, it should include the LinkedIn profile, role, company details, and the signal that explains why outreach is happening now. If the list is wrong, every downstream metric gets noisy.
Operator rule: connect who to contact, how to reach them, and what happened next. Anything else is decoration.
What to verify before you buy
If you want a cleaner vendor comparison, picking the right orchestration platform is useful reading because it pushes past feature lists. In practice, I'd check for state management, retry logic, audit trails, clear ownership controls, and a way to see failures without opening three tools.
Evaluation factor | Why it matters | What to verify |
|---|---|---|
Ownership model | Prevents cross-team ambiguity | Who owns workflow reliability and escalation |
Dependency handling | Avoids broken execution order | DAG support and task-level prerequisites |
Recovery behavior | Protects downstream systems | Retry policies, quarantine, and replay |
Compliance logging | Preserves decision evidence | Inputs, rules, overrides, and timestamps |
Cost visibility | Makes ROI measurable | Per-workflow cost and failed-run cost |
CRM handoff | Turns work into pipeline | Clear rules for lead, account, and meeting routing |
Protecting deliverability matters too. Outbound should run on separate sending domains with daily limits so scaling volume doesn't put the main domain at risk. That's not orchestration in the abstract, it's orchestration applied to revenue operations.
If you're ready to tighten this up, audit your meeting-held rate this Friday and trace every dropped opportunity back to the step where the data stopped being trusted. If you want help turning that audit into a working system, Grou builds the connected outbound and pipeline layer around the same structure, then reviews it in bi-weekly sprints so gaps show up fast, not at quarter end.
Your stack is busy, but your pipeline still feels blind. Leads land in LinkedIn, email, paid channels, and your CRM. Replies split across inboxes. Hand-offs stall. By the time someone asks why qualified meetings are flat, the team is already arguing over whose report is right.
The core issue is usually coordination, not volume. Fragmented systems make ownership, failures, and dependencies harder to see.
A data orchestration platform gives revenue teams state, retries, and traceability. That's what turns scattered activity into a controlled pipeline.
The buying decision is as much about governance as tooling. Ownership, definitions, and escalation paths matter more than feature checklists.
The practical test is simple. If your stack can't explain what ran, what broke, and what reached CRM, it's not ready.
For teams who need gain visibility into your sales pipeline, the pattern is familiar. You can see activity everywhere, but you can't trust the handoff from signal to revenue. GROU sees the same problem in iGaming, SaaS, manufacturing, legal tech, and pharma, and the fix starts with structure, not more tools. See also data hygiene.
Table of Contents
How orchestration differs from ETL, ELT, and basic workflows
Use cases across iGaming, SaaS, manufacturing, legal tech, and pharma
Why pipeline data usually breaks before it reaches revenue
A rep replies in Gmail, a marketer sees engagement in LinkedIn, and the CRM still shows a stale stage. That mismatch is where pipeline data usually breaks. One system records activity, another assigns ownership, and a third waits for a clean update that never arrives.
The result is familiar in RevOps. Activity reports can look healthy while qualified meetings stay flat, because the stack rewards motion instead of outcomes. Sends rise, clicks rise, connection requests rise, and the team still cannot explain why the pipeline is not moving.
Practical rule: if the same prospect exists in three tools with three different statuses, the problem is orchestration.
Clean reporting starts with visibility, then coordination, then tooling. Many teams try to fix the last step first, which only adds more software on top of the same disconnect. If you need a deeper explanation of the pattern, gain visibility into your sales pipeline is a solid companion read.
For revenue teams, the failure usually shows up in ordinary work. A form fill should route to the right owner. A positive reply should reach sales fast. A bad enrichment call should not pollute the CRM. A missed dependency can break all four, and the issue often stays hidden until a forecast review or a quarter-end scramble.
That is also why data hygiene matters here. Clean inputs, clear ownership, and consistent definitions keep orchestration useful instead of turning the stack into a junk drawer. When those basics slip, outbound signals scatter, routing gets unreliable, and qualified pipeline becomes harder to trust.
What a data orchestration platform does
A serious orchestration layer treats work as a directed acyclic graph, or DAG. Each node is a task. Each edge is a dependency. That structure matters because the scheduler only triggers what is ready, and a revenue stack cannot afford random execution order.
The control plane decides, the workers execute
The split that matters is scheduling versus execution. The control plane checks state. The executor runs the work. That separation keeps slow jobs from blocking fast decisions, which matters when one path is a quick reply router and another is a slower enrichment or scoring job.
Apache Airflow makes that separation explicit through its scheduler, executor, webserver, DAG definitions, and metadata database, and its DAG abstraction models task dependencies, data flow, and retries (Airflow architecture overview). That structure gives you a traceable record of what ran, when it ran, and why a task retried.
For revenue operations, the same pattern coordinates enrichment, deduplication, scoring, CRM sync, attribution, and alerts without turning each step into its own island. A workflow only helps if the system can preserve order, retry safely, and show where the chain broke. That is why a low-code wrapper can be useful, but only if the dependency model underneath is real, as explained in how a low code platform works. See our GTM orchestration overview for how this maps to pipeline workflows.
Idempotency is the feature that saves you later
The quiet requirement is idempotency. If a task reruns, it should not duplicate a record or fire the same downstream action twice. That is not a nice-to-have. It keeps a failed enrichment retry from sending duplicate alerts or updating the CRM incorrectly.
One clean retry policy beats three manual fixes after the fact.
Orchestration differs from a pile of scripts because scripts can move data, while orchestration preserves state, manages dependency order, and makes failure visible before it corrupts a downstream handoff. For B2B teams, that is the difference between a reliable pipeline and a set of disconnected automations.
How orchestration differs from ETL, ELT, and basic workflows
ETL and ELT describe movement and transformation. Orchestration sits above them and decides how the whole chain behaves when conditions change. That's why the recommendation is straightforward, not neutral.
Pick the layer that matches the job
Use ETL or ELT when the main task is data movement or transformation. Use a workflow engine when the sequence is simple and linear. Choose a data orchestration platform when the stack has many dependencies, retries, handoffs, and audit needs that can't be handled well by a straight-line job.
Option | What it does well | Where it falls short |
|---|---|---|
ETL or ELT | Moving and transforming data | Weak on dependency control and failure isolation |
Basic workflow tools | Linear task sequences | Limited state management and replay logic |
Data orchestration platform | Coordinating distributed steps with retries and observability | More setup, but far better control |
For mid-market B2B pipeline stacks, the verdict is usually clear. If you're only moving a few datasets on a schedule, a lighter tool is fine. If lead routing, enrichment, CRM sync, attribution, and reporting all depend on one another, orchestration earns its place quickly.
That's the line many teams cross when they grow out of ad-hoc jobs. They no longer need “something that runs.” They need something that can explain what happened, recover cleanly, and keep downstream systems from acting on broken inputs. The distinction is easy to miss until the first serious incident.
See the workflow glossary entry if you want a quick shorthand for how a workflow differs from a coordinated orchestration layer.
Core capabilities that matter for B2B pipeline teams
The most useful capabilities are the ones that keep bad records out of the CRM and keep good records moving. That starts with a single target list, shared by outreach and reporting, so one prospect doesn't become three conflicting versions of truth. It also means route rules, scoring logic, and attribution updates have to behave the same way every time.
The capabilities that protect revenue quality
Capability | Pipeline impact | When it matters most |
|---|---|---|
Verified prospect data | Reduces wasted sends and bad routing | Before first outreach goes live |
Unified reply tracking | Prevents channel-level blind spots | When email and LinkedIn run together |
Explicit enrichment and scoring rules | Keeps ad-hoc scripts out of the core motion | When handoffs depend on qualification |
Retry and quarantine logic | Stops broken tasks from polluting CRM | When upstream vendors or APIs fail |
Audit logging | Preserves decision history for compliance | When prospect data affects routing or suppression |
A failed enrichment call should not push incomplete records downstream. It should retry under a defined policy, then quarantine if the error persists. That's a lot less glamorous than “automation,” but it's what keeps sequences from firing on bad data.
Recovery mechanics matter more than glossy dashboards
Documented enterprise workflow behavior includes detecting failure, applying retry policies, isolating the failed step, and resuming from the right recovery point rather than restarting the whole pipeline (enterprise workflow recovery behavior). That's the difference between a controlled exception and a silent data mess.
For teams handling European prospect data, compliance logging matters just as much. UK GDPR guidance says that when solely automated processing produces a legal or similarly significant effect, people need safeguards including human intervention, the ability to express their viewpoint, the ability to contest the decision, and access to an explanation of the logic (UK GDPR guidance on AI systems). CNIL also says personal data must be appropriate, relevant, and limited to what's necessary for the purpose, with human review available where automated decisions are used (CNIL guidance on AI and GDPR).
See the RevOps tech stack guide if you want to place orchestration in the rest of the stack, not treat it like a standalone toy.
Use cases across iGaming, SaaS, manufacturing, legal tech, and pharma
Orchestration shows its value when one revenue motion depends on several signals at once. In iGaming, that usually means ad engagement, intent, and outbound activity feeding the same pipeline. In SaaS, the difference is visible in the handoff, a list that produces replies is not the same as a list that produces accepted meetings.
iGaming and adjacent demand capture
Sportradar needed a structured way to capture demand from sportsbooks and betting companies across EMEA. Campaigns ran across LinkedIn, Google, Reddit, RichAds, and 6sense, all feeding one pipeline instead of separate reports. Reported results from that demand-capture program included 800+ qualified leads at €15 per lead, with 80% qualifying as SQLs (Sportradar example).
The point is not which channel “won.” The point is that one pipeline made the mix measurable. Without that structure, each source ends up in its own dashboard, with its own story, and RevOps has no clean way to connect spend to meetings. For teams working in iGaming, this industry page shows how the same coordination problem shows up across demand capture, lead handling, and reporting.
What the unified motion exposes
Unified data makes it easier to see where multichannel outreach beats email-only programs. MBF saw that pattern in its own outreach, and T-2's IT segment reached a 19.2% reply rate, compared with an 11.8% average, once email and LinkedIn were measured in one list. A source that discusses practical workflow coordination in similar programs is the reply-rate example.
The same structure matters in manufacturing, legal tech, and pharma, even when the message changes. The core work is keeping source, message, response, and CRM outcome tied together. Without that chain, attribution becomes decoration instead of a decision tool.
Ownership, not connector work, is where these projects stall. A 2026 survey found that legacy systems and technical debt were the leading bottleneck at 25.4%, followed by lack of leadership direction at 21.3% and poor requirements or upstream issues at 18.8%. Tool complexity was only 2.7%, which points to a familiar RevOps problem, the stack is rarely the hardest part, alignment is. (survey on data engineering bottlenecks)
How to evaluate and implement a data orchestration platform
Start with governance, not features. If nobody agrees on what counts as a sales-accepted lead, an SQL, or an attributed pipeline touch, the platform just automates disagreement. Ownership, escalation paths, and handoff rules need to be settled before any vendor demo starts.
The second filter is cost visibility. A 2026 survey of 113 data professionals found that 44 percent of organizations spent between $25,000 and $100,000 per month on their data stack, while only 12 percent felt they were receiving strong ROI from it (survey on data stack costs). That makes workload-level attribution essential, because a single platform can hide waste if nobody tracks what each pipeline really costs.
A practical implementation sequence
Start with three sources in this order, because the dependency chain matters. First, verified prospect data. Second, outreach activity across email and LinkedIn. Third, the CRM. That sequence keeps the target list, the message, and the outcome tied together from the start.
The order matters because data quality decides deliverability, reply rate, and lead quality. Each record should carry more than a name and email, it should include the LinkedIn profile, role, company details, and the signal that explains why outreach is happening now. If the list is wrong, every downstream metric gets noisy.
Operator rule: connect who to contact, how to reach them, and what happened next. Anything else is decoration.
What to verify before you buy
If you want a cleaner vendor comparison, picking the right orchestration platform is useful reading because it pushes past feature lists. In practice, I'd check for state management, retry logic, audit trails, clear ownership controls, and a way to see failures without opening three tools.
Evaluation factor | Why it matters | What to verify |
|---|---|---|
Ownership model | Prevents cross-team ambiguity | Who owns workflow reliability and escalation |
Dependency handling | Avoids broken execution order | DAG support and task-level prerequisites |
Recovery behavior | Protects downstream systems | Retry policies, quarantine, and replay |
Compliance logging | Preserves decision evidence | Inputs, rules, overrides, and timestamps |
Cost visibility | Makes ROI measurable | Per-workflow cost and failed-run cost |
CRM handoff | Turns work into pipeline | Clear rules for lead, account, and meeting routing |
Protecting deliverability matters too. Outbound should run on separate sending domains with daily limits so scaling volume doesn't put the main domain at risk. That's not orchestration in the abstract, it's orchestration applied to revenue operations.
If you're ready to tighten this up, audit your meeting-held rate this Friday and trace every dropped opportunity back to the step where the data stopped being trusted. If you want help turning that audit into a working system, Grou builds the connected outbound and pipeline layer around the same structure, then reviews it in bi-weekly sprints so gaps show up fast, not at quarter end.
Pipeline OS Newsletter
Build qualified pipeline
Get weekly tactics to generate demand, improve lead quality, and book more meetings.



Trusted by industry leaders
Trusted by industry leaders
Trusted by industry leaders
Ready to build qualified pipeline?
Ready to build qualified pipeline?
Ready to build qualified pipeline?
Book a call to see if we're the right fit, or take the 2-minute quiz to get a clear starting point.
Book a call to see if we're the right fit, or take the 2-minute quiz to get a clear starting point.
Book a call to see if we're the right fit, or take the 2-minute quiz to get a clear starting point.
" height="30.21639343089746px" id="hfGbXmQR2" width="30.216393430897455px"/></svg>)
Copyright © 2026 – All Right Reserved
Copyright © 2026 – All Right Reserved
Copyright © 2026 – All Right Reserved